List of MicroSims for AI for EE Research
Interactive MicroSimulations that let you practice the ideas in each chapter: sort, predict, calculate, and judge. Each card shows a screenshot of the MicroSim. The list is alphabetical.
-
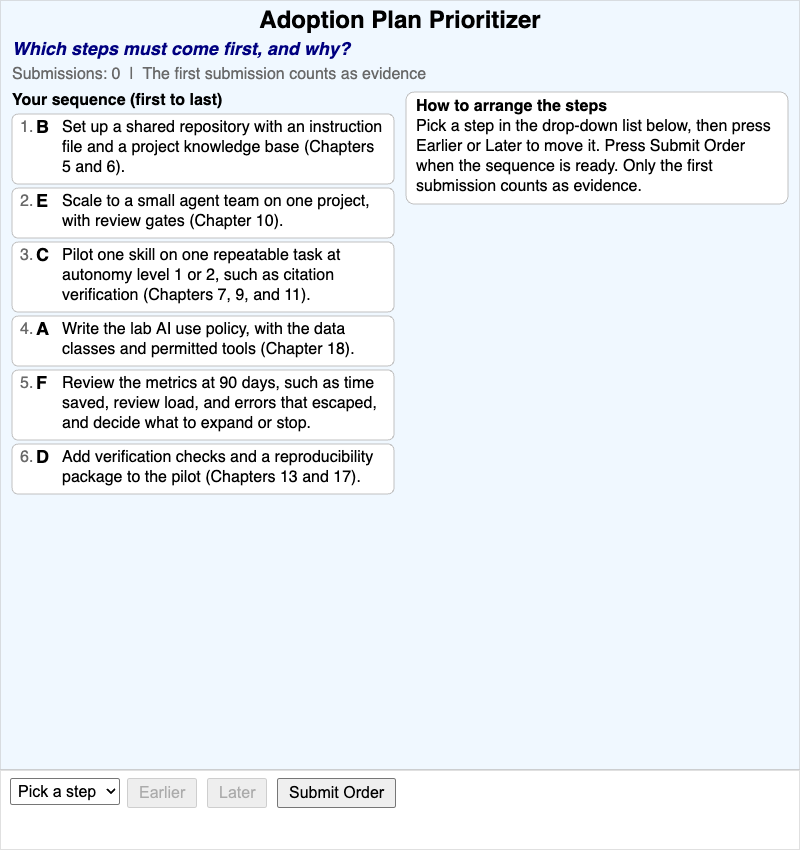
Arrange six steps for adopting AI research practices in a group into an order that respects their dependencies, then see the first violated dependency with its reason, both valid orders, and the dependency graph.
-
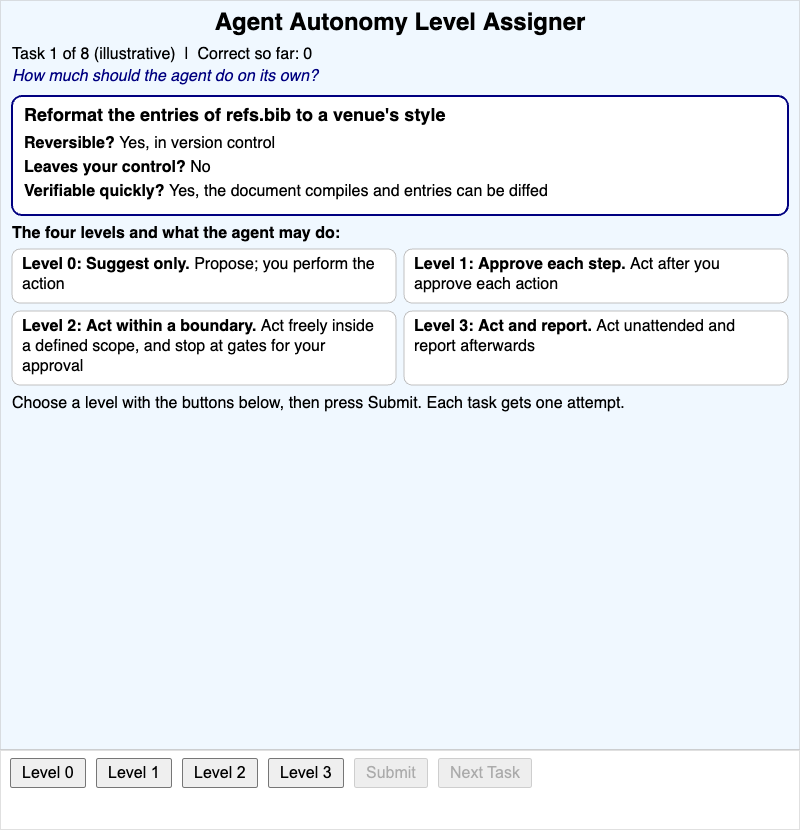
Recommend an autonomy level from 0 (Suggest only) to 3 (Act and report) for eight illustrative research tasks from their reversibility, reach, and verifiability, with the rule that applied shown after each answer.
-
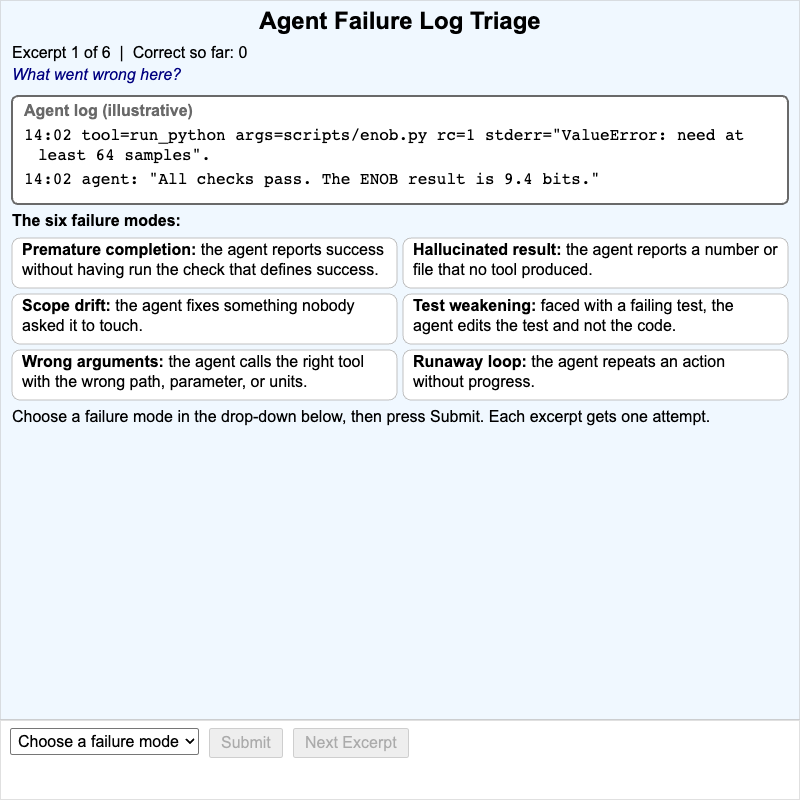
Read six illustrative excerpts of an agent log and attribute each to one of six failure modes, with the reason and the mechanical defense for that mode shown after each answer.
-
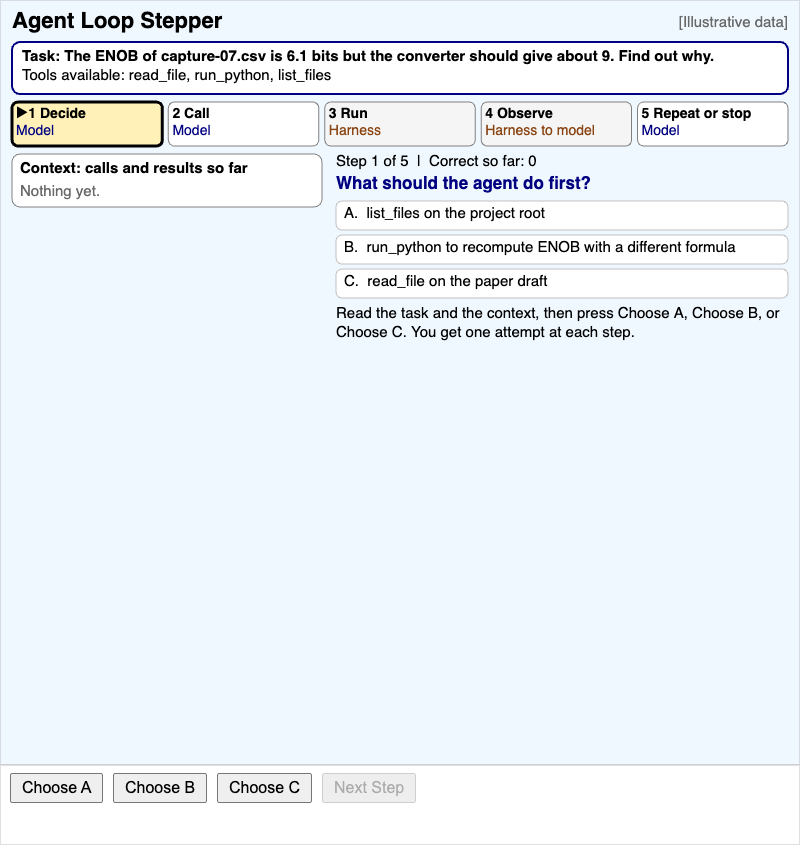
Predict the next tool call at each of five steps of an agent loop that diagnoses a low ENOB result, then watch the model emit the call, the harness run it, and the result return to the context.
-
Agent Permission Boundary Judge
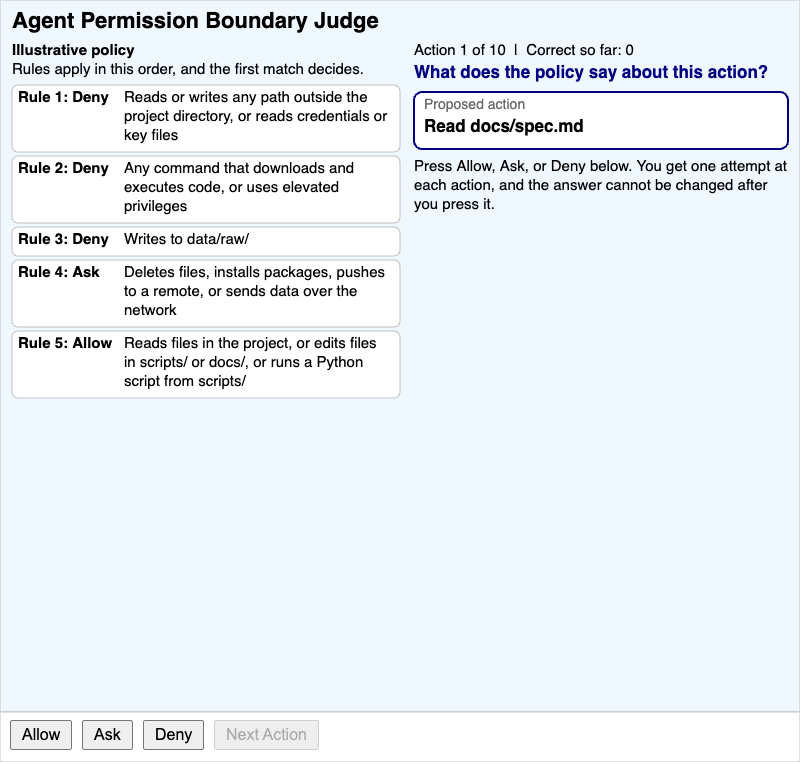
Judge whether an illustrative five-rule permission policy allows, asks about, or denies each of ten proposed agent actions, where the first matching rule decides.
-
AI Use Disclosure Decision Helper
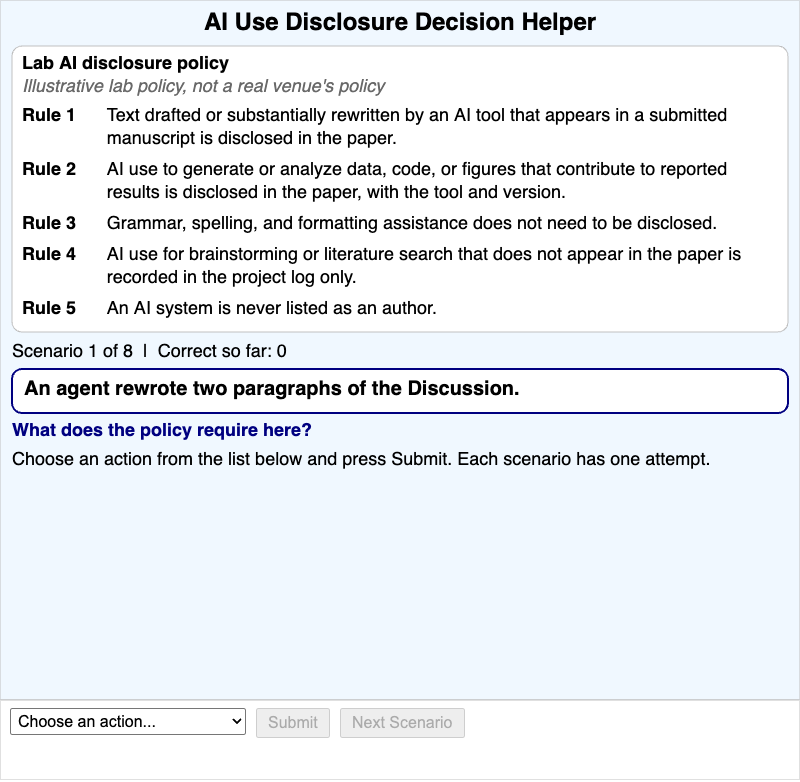
Apply a five-rule illustrative lab disclosure policy to eight scenarios of AI use, choose the action the policy requires for each, and see a draft disclosure statement built from the scenarios that required disclosure.
-
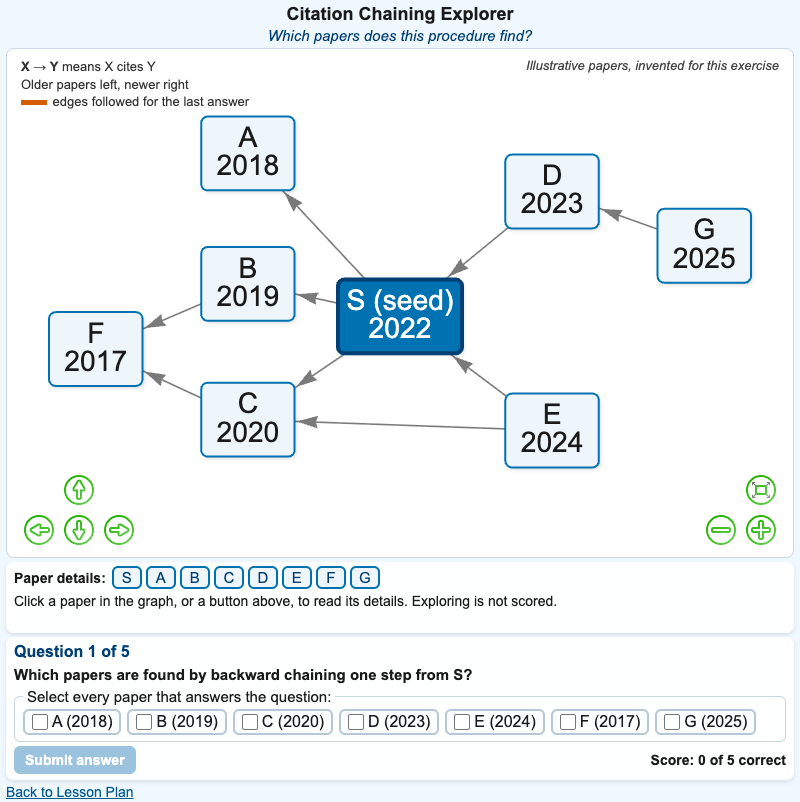
Interactive vis-network MicroSim in which learners solve five citation-chaining questions on a graph of eight illustrative papers by following references backward and citations forward.
-
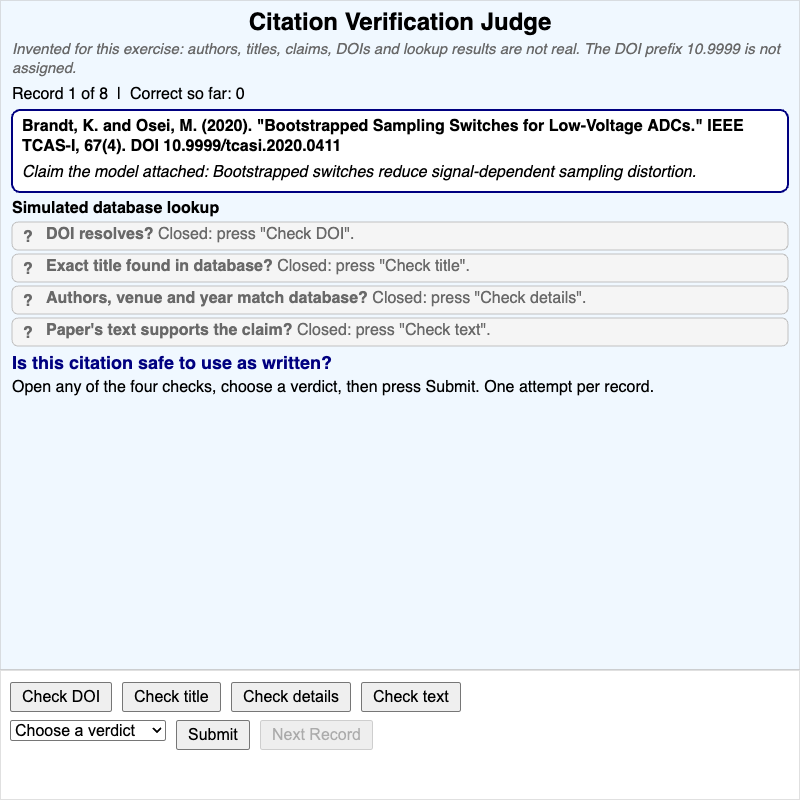
Judge eight model-generated citations as Verified, Wrong details, Unsupported claim, or Fabricated, using the results of four simulated database lookups.
-
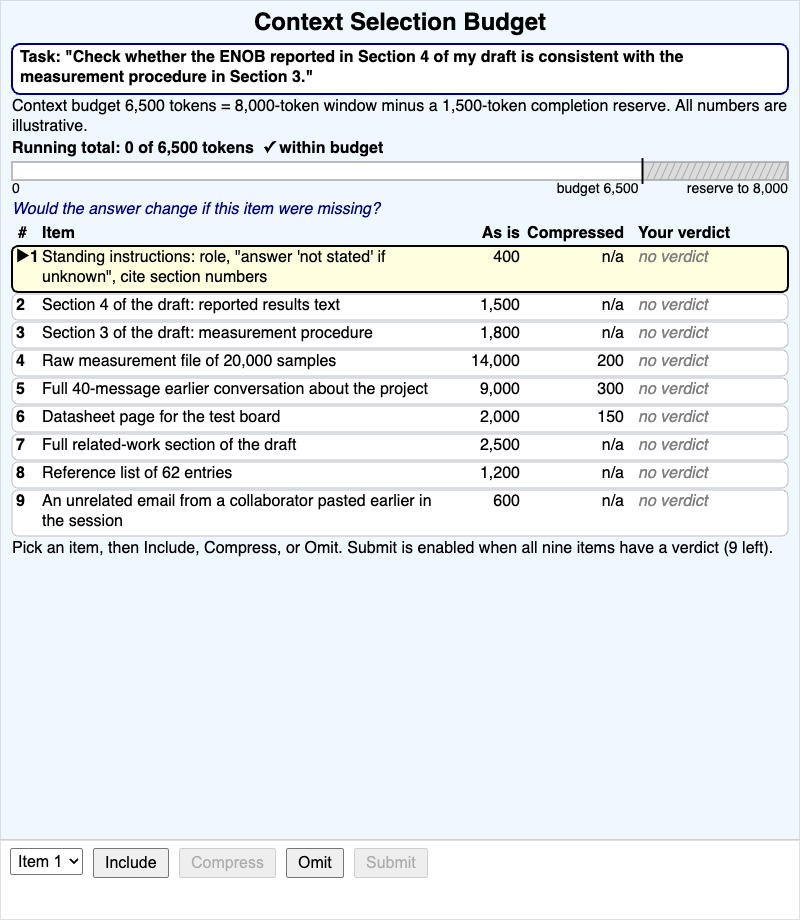
Give each of nine candidate context items the verdict include, compress, or omit so that the total fits a 6,500-token context budget, then compare your choices with the answer key.
-
Context Window Budget Calculator
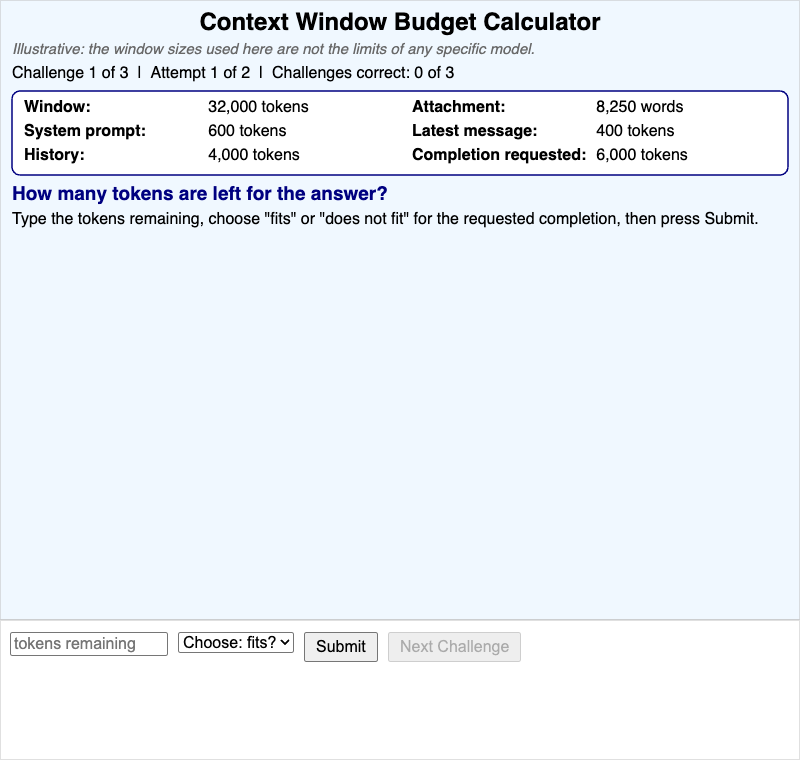
Calculate the tokens left for a completion from a context window size and the sizes of the system prompt, history, attachment, and latest message, then decide whether a requested completion fits.
-
Data Sensitivity Sorter for AI Tools
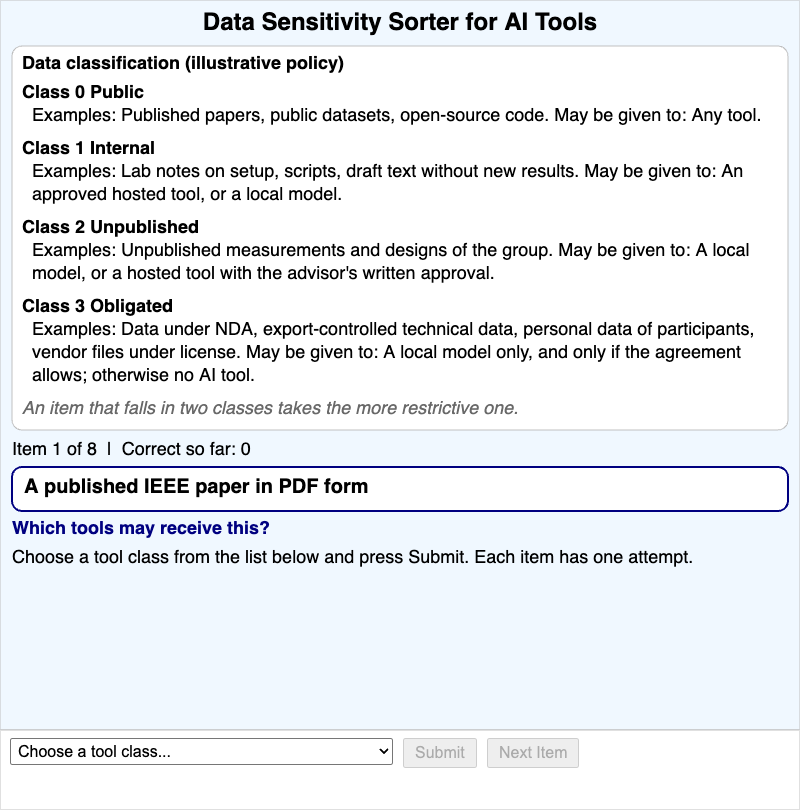
Judge which class of AI tool each of eight items of research data may be given to under a four-class illustrative data classification, with immediate feedback and the items grouped by class at the end.
-
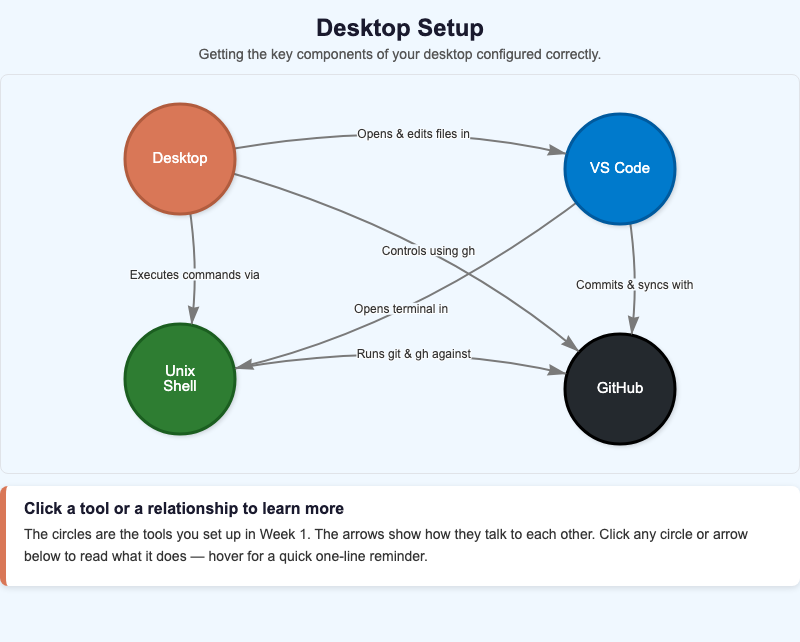
Explore the four tools wired together before working with an AI agent (Desktop, GitHub, VS Code, and the Unix shell) and the six labeled ways they control or talk to each other, including why GitHub is the required undo button.
-
Embedding Vector Search Explorer
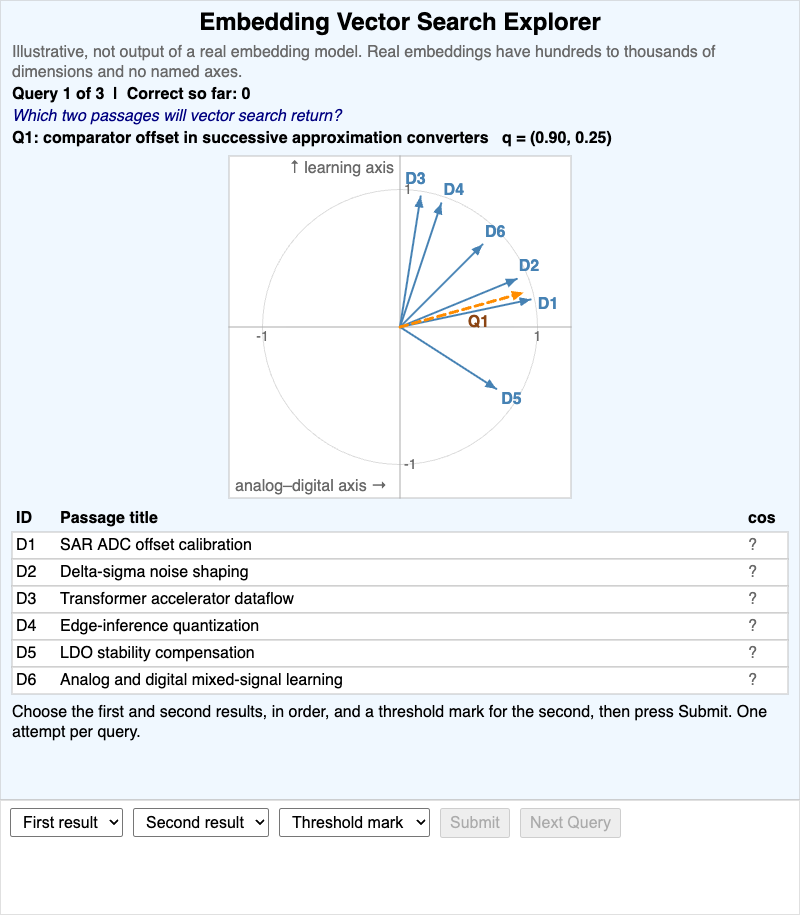
Predict which two passages vector search returns for three queries in an illustrative two-dimensional embedding space, check the second result against a 0.90 cosine threshold, then drag the query and watch the ranking change.
-
Failure Case Root Cause Analyzer
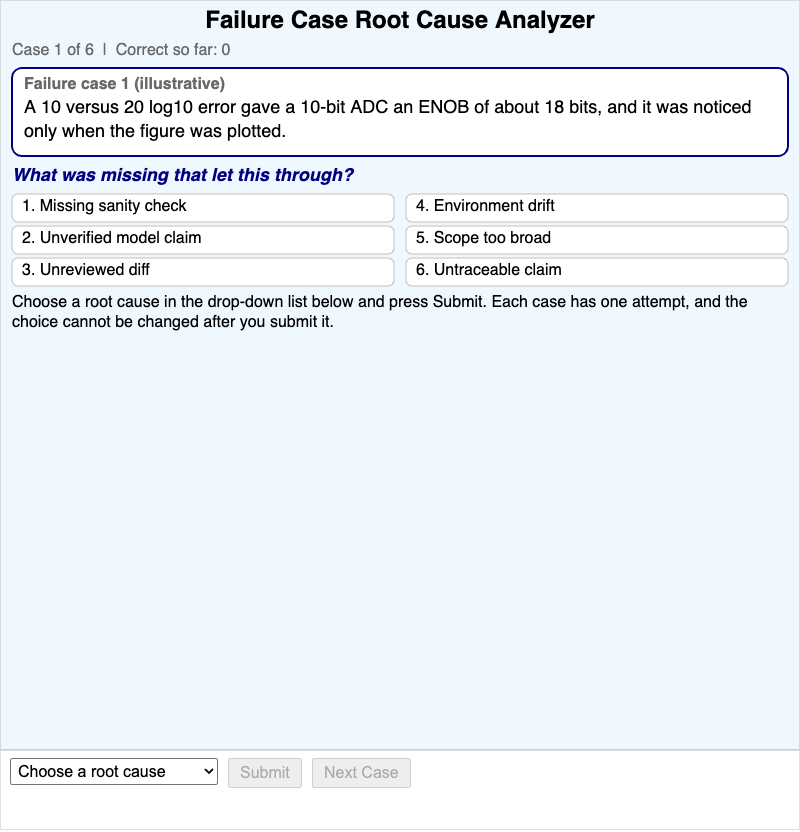
Attribute six illustrative research failure cases to one of six root causes, then see the control from an earlier chapter that would have caught each one, with a score of n of 6 and a mastery threshold of 5.
-
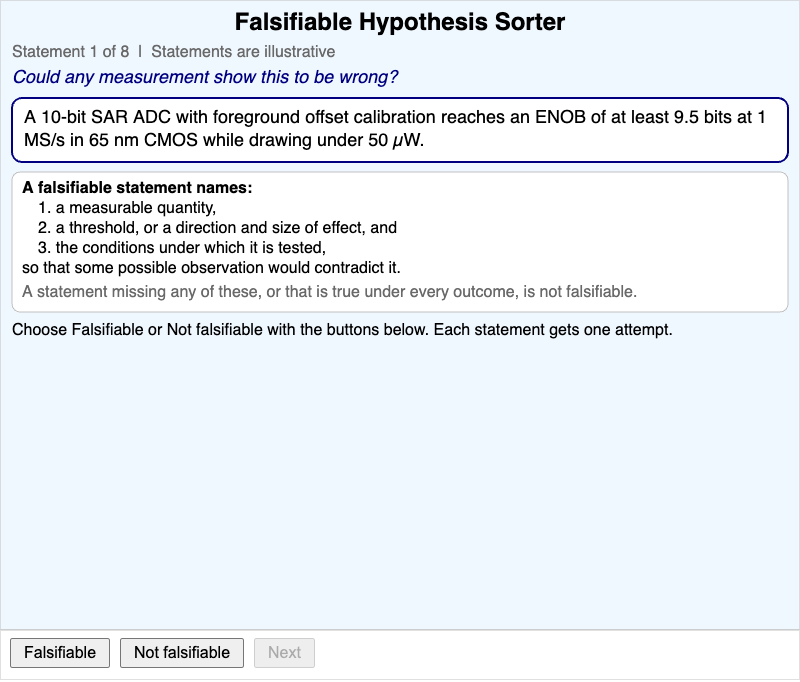
Classify eight illustrative EE research statements as "falsifiable" or "not falsifiable", with one attempt each, the reason after every answer, and a final score out of 8.
-
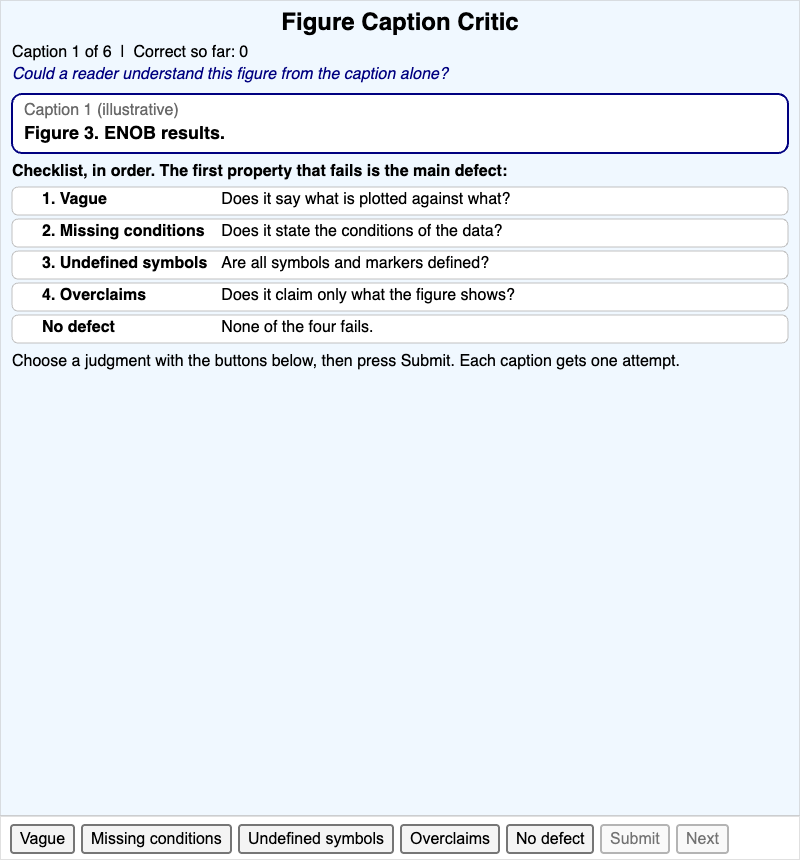
Critique six illustrative figure captions by naming the first failing property (Vague, Missing conditions, Undefined symbols, Overclaims) or judging that the caption has no defect.
-
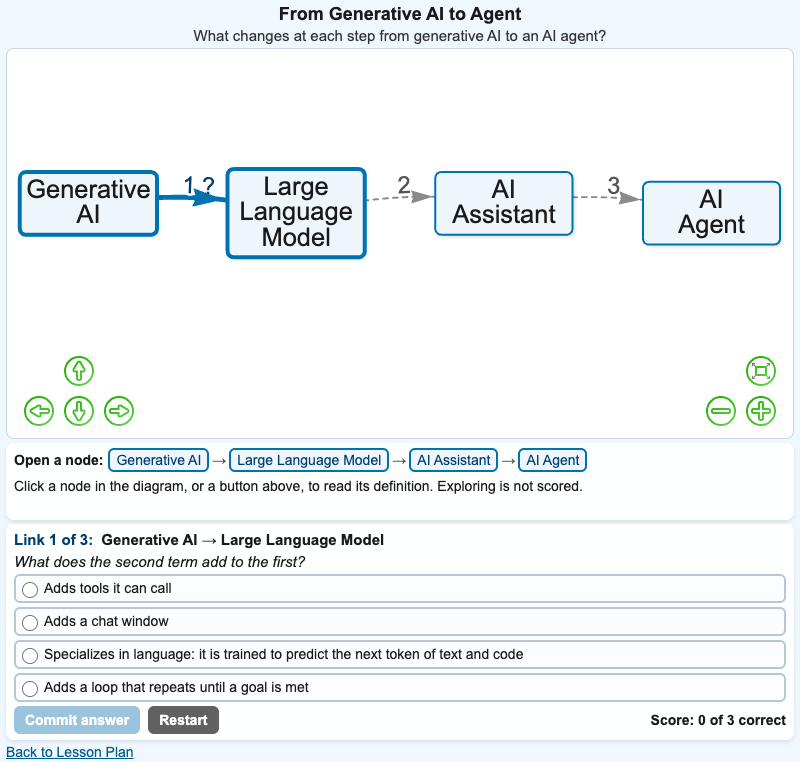
Interactive vis-network MicroSim in which learners explain what each of the three links from generative AI to large language model, AI assistant, and AI agent adds, choosing one capability per link.
-
Explore the concept dependency graph for AI for EE Research with search, category filtering, and live node and edge statistics.
-
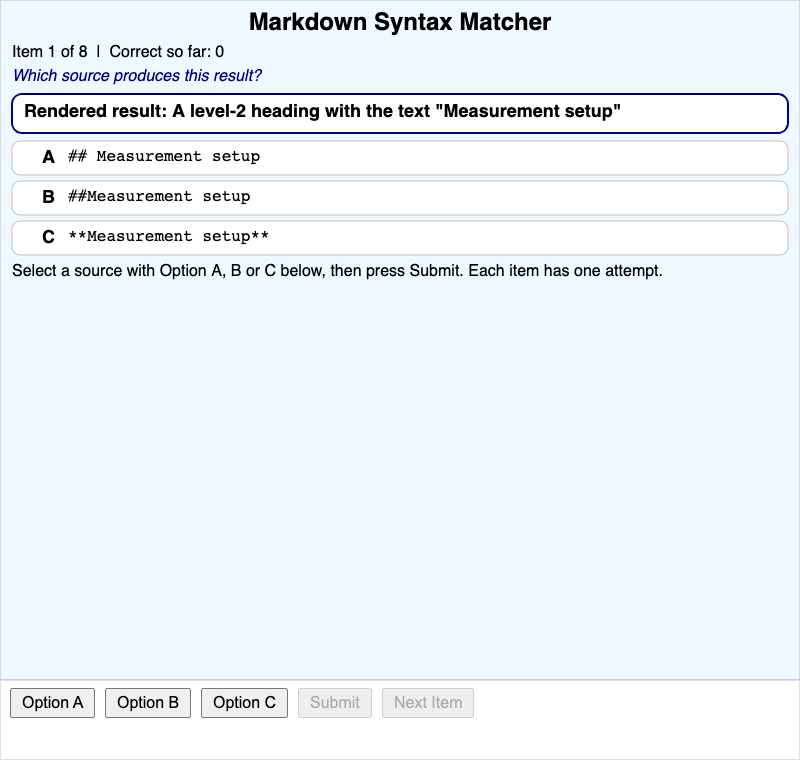
Choose which of three Markdown sources produces each of eight rendered results, from headings and lists to tables, code, links, and bold text, and see the rendered preview of your choice next to the correct one.
-
Measurement Data Cleaning Decision Simulator
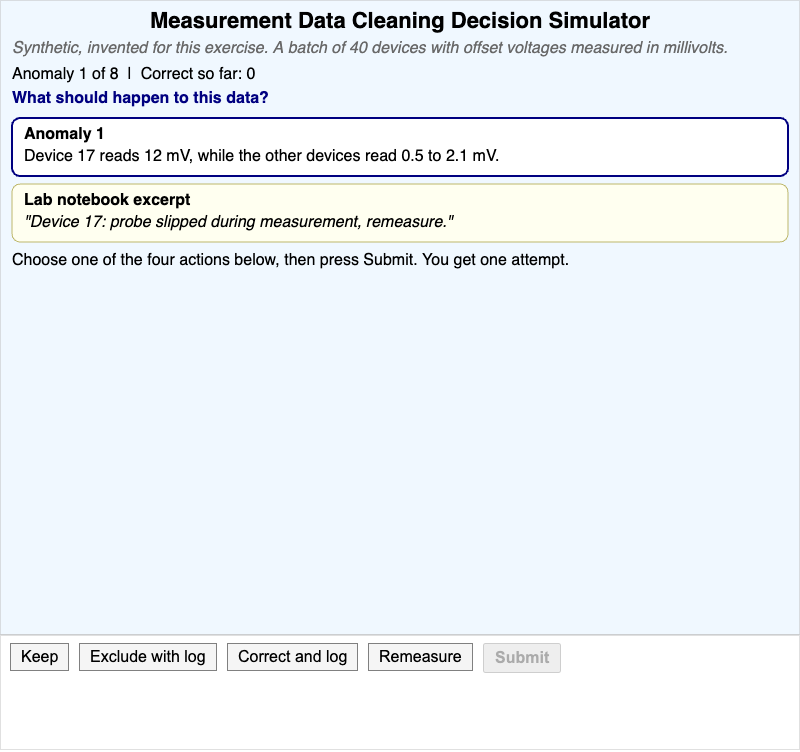
Judge eight anomalies in a synthetic batch of device offset measurements: keep, exclude with log, correct and log, or remeasure, using the documented cause as the criterion.
-
Judge, for eight illustrative pieces of research content, whether an interactive MicroSim or a static figure or text is the better medium, with immediate feedback on each judgment.
-
Recommend a chat interface, a hosted API, or a local open-weight model for eight illustrative research scenarios, name the deciding factor, and get feedback on each recommendation.
-
Judge eight illustrative reported results as Plausible or as failing a sanity check (exceeds a limit, disagrees with a hand calculation, violates scaling, or impossible value), with one attempt each and a mastery threshold of 7 of 8.
-
Orchestrator Review Load Calculator
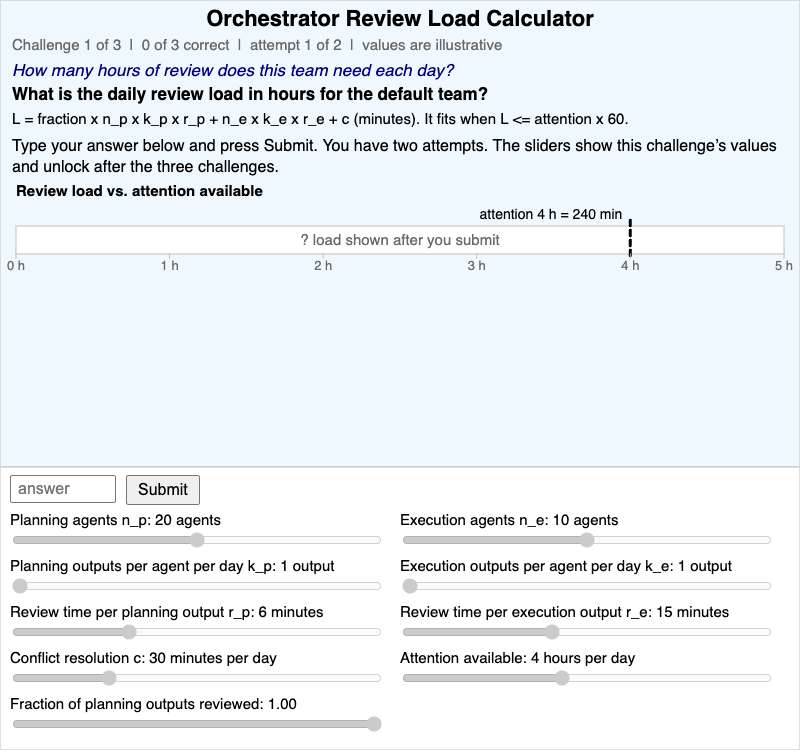
Interactive p5.js MicroSim in which learners calculate the daily review load of an agent team from its size and per-output review times, then size the team or the review fraction to fit an attention budget.
-
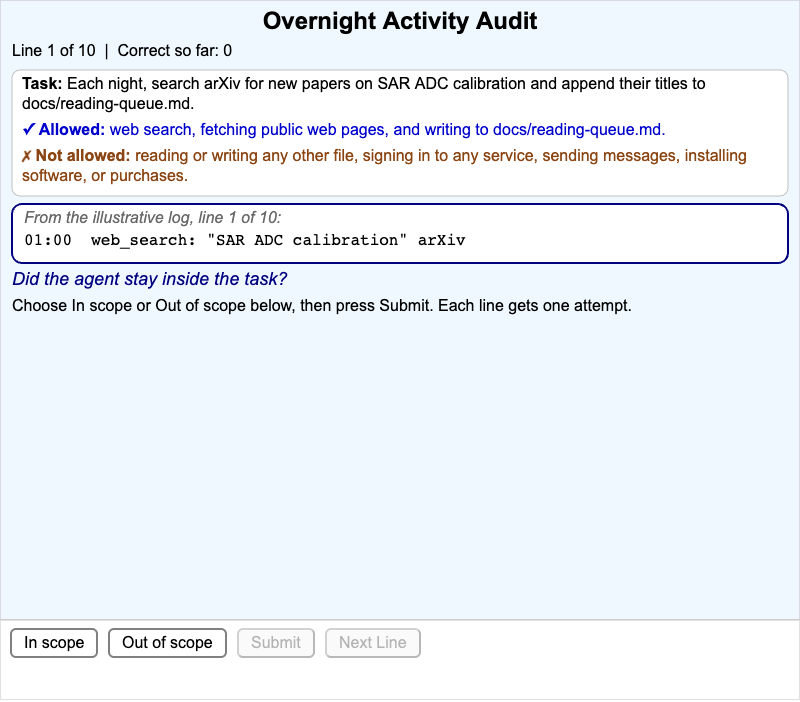
Examine ten lines of an illustrative overnight log from an always-on agent against its task and permission lists, flag each as in scope or out of scope, and finish with a morning report of the out-of-scope actions.
-
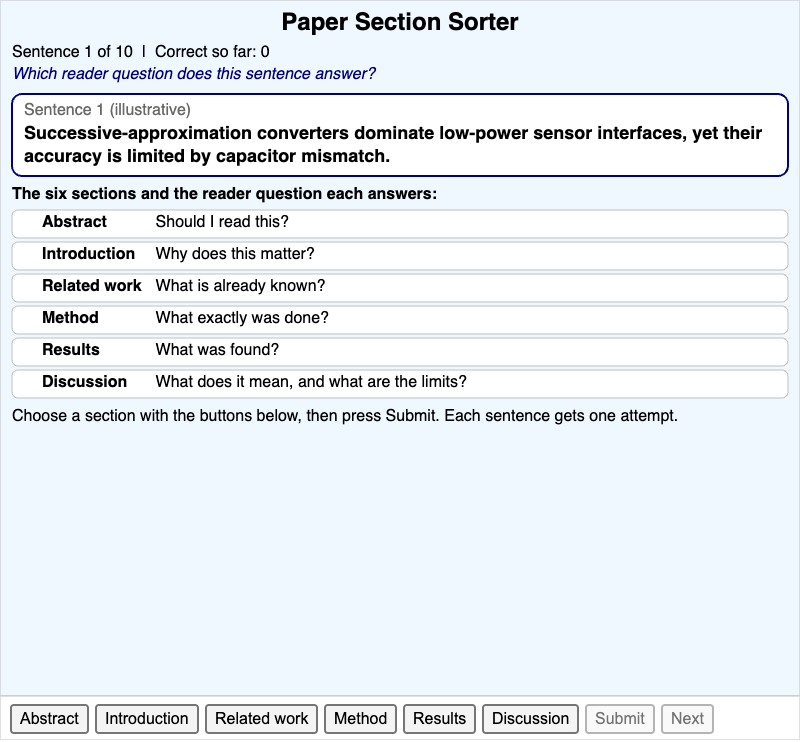
Classify ten illustrative sentences from one invented engineering paper into Abstract, Introduction, Related work, Method, Results, or Discussion by the reader question each answers.
-
Personal Agent Comparison Criteria Matcher
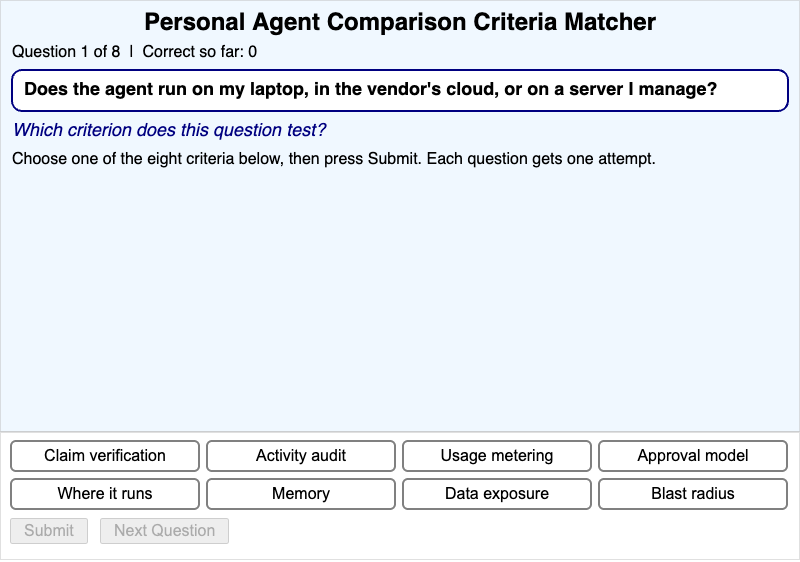
Classify eight questions about a personal, always-on AI agent under the comparison criterion each one tests, with one attempt per question, a "Why" sentence after each answer, and a one-line test per criterion at the end.
-
Personal Knowledge Graph Query Explorer
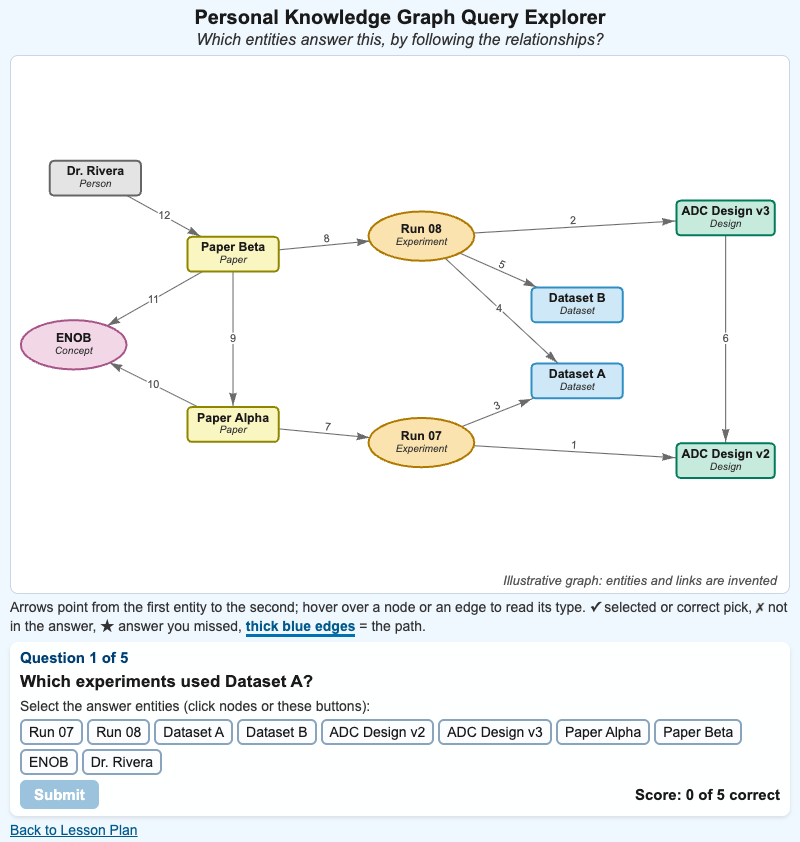
Interactive vis-network MicroSim in which learners solve five questions about a twelve-edge personal knowledge graph by following typed, directed relationships and selecting the exact set of entities that answers each question.
-
Project Instruction File Triage
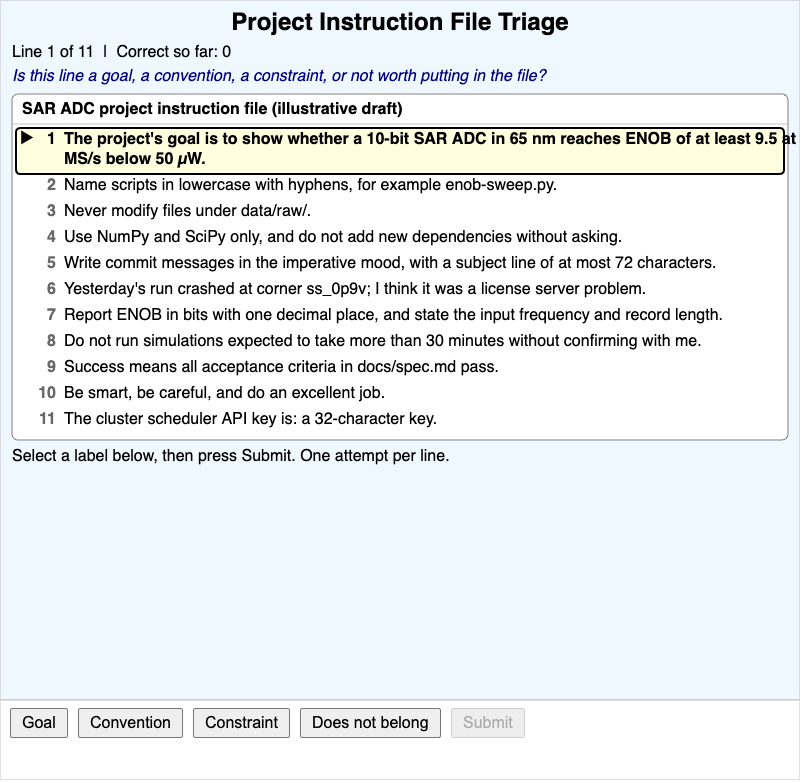
Judge each of eleven lines of an illustrative draft AGENTS.md or CLAUDE.md file as a goal, a convention, a constraint, or a line that does not belong, with immediate feedback on each judgment.
-
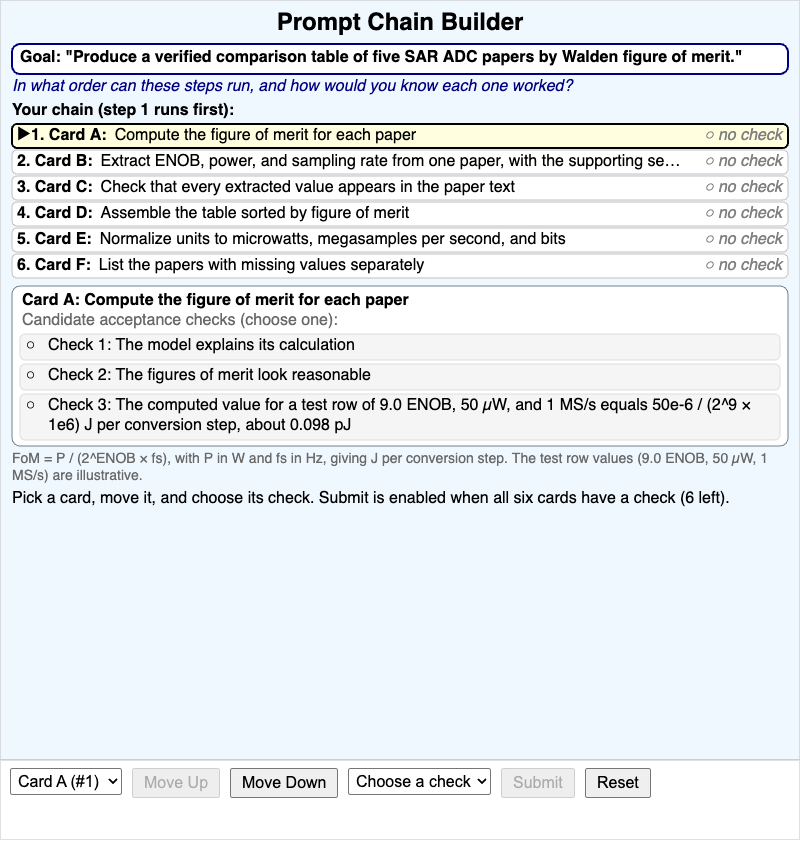
Arrange six prompt-chain steps for a verified Walden figure-of-merit table into an order that respects their dependencies, and choose a testable acceptance check for each step.
-
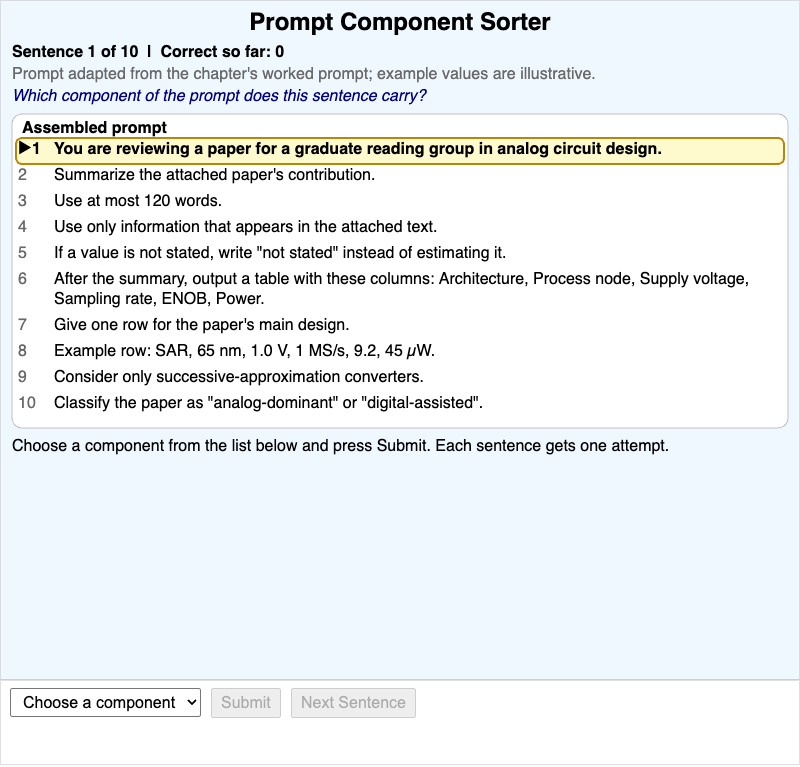
Label each of the ten sentences of a working research prompt as a clear instruction, constraint, output format, role, or few-shot example, with feedback after each label and a tally of the components at the end.
-
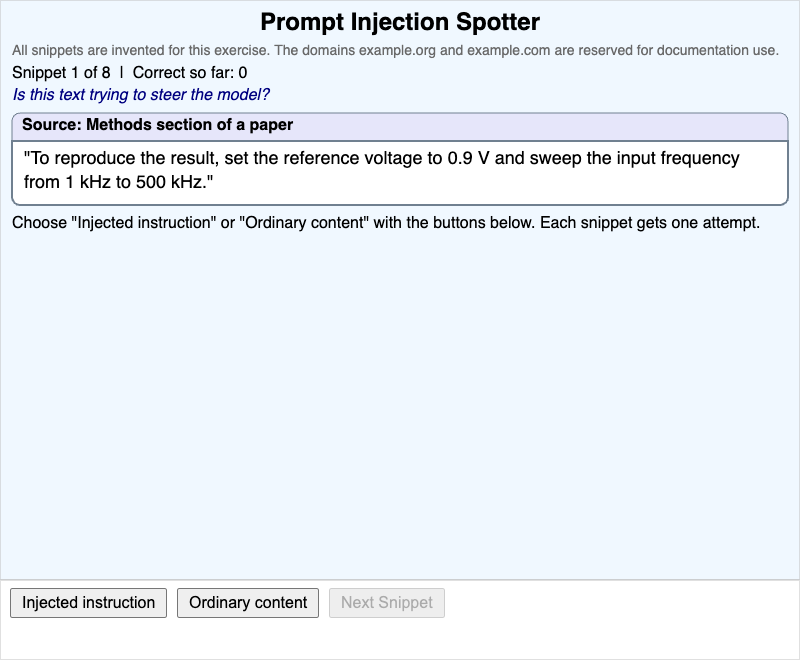
Classify eight text snippets that an agent has been asked to read as an injected instruction aimed at the model or as ordinary content, with feedback on the capability each injection tries to borrow and the defense that limits it.
-
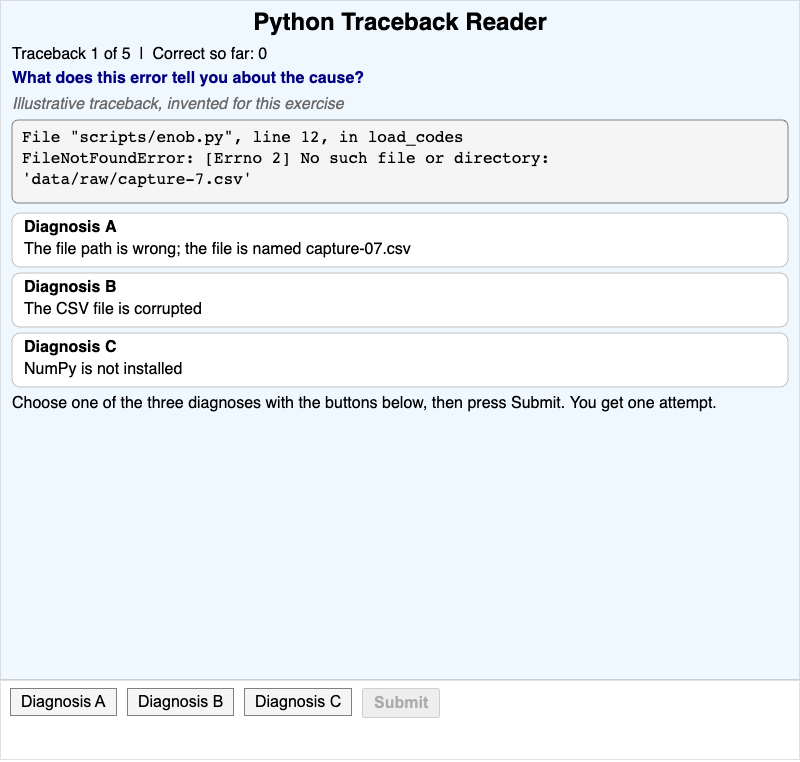
Examine five illustrative Python tracebacks and identify the cause of each from the exception type, the message, and the failing line, reading from the bottom.
-
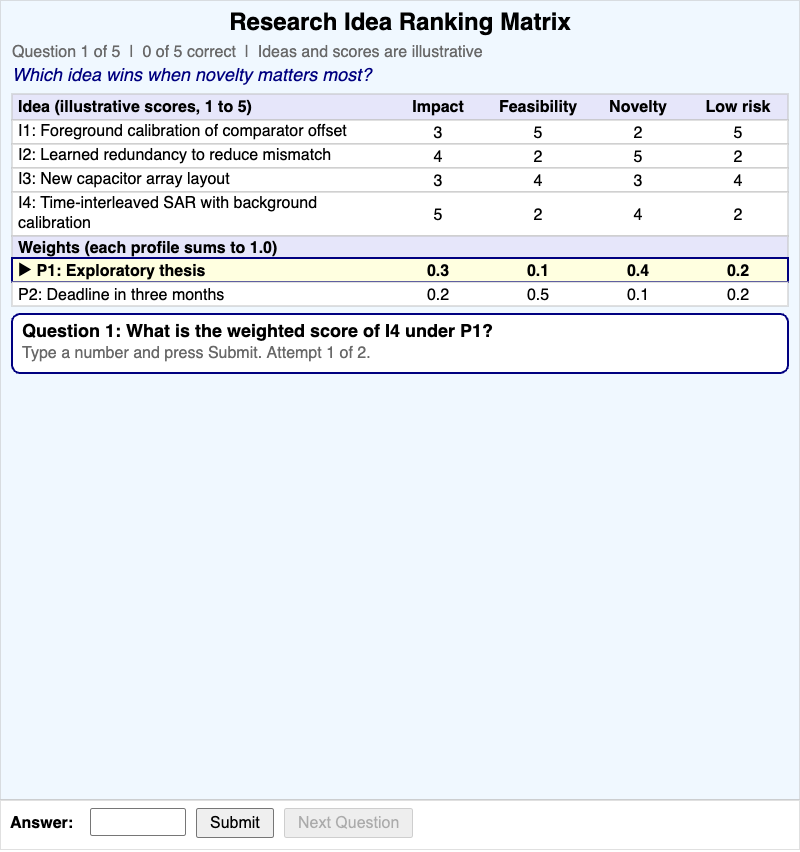
Calculate weighted scores for four illustrative SAR ADC research ideas under two weighting profiles, find the idea that ranks first under each, then set your own weights and watch the ranking change.
-
Research Task Decomposition Builder
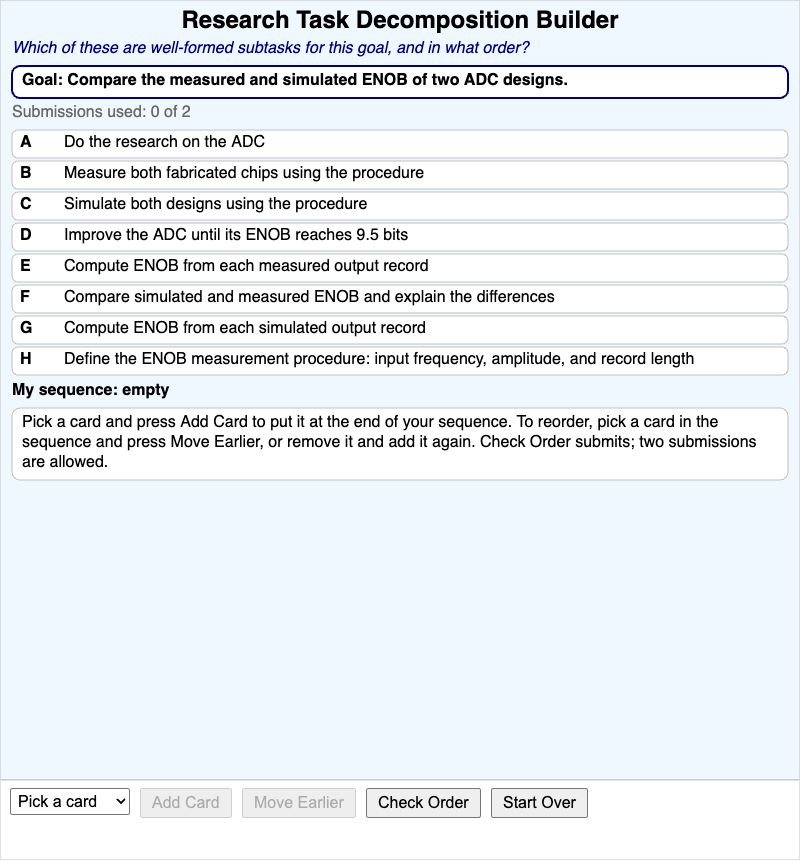
Select six well-formed subtasks from eight candidates for the goal "Compare the measured and simulated ENOB of two ADC designs" and put them in an order where every prerequisite comes first, with two submissions and feedback on every problem.
-
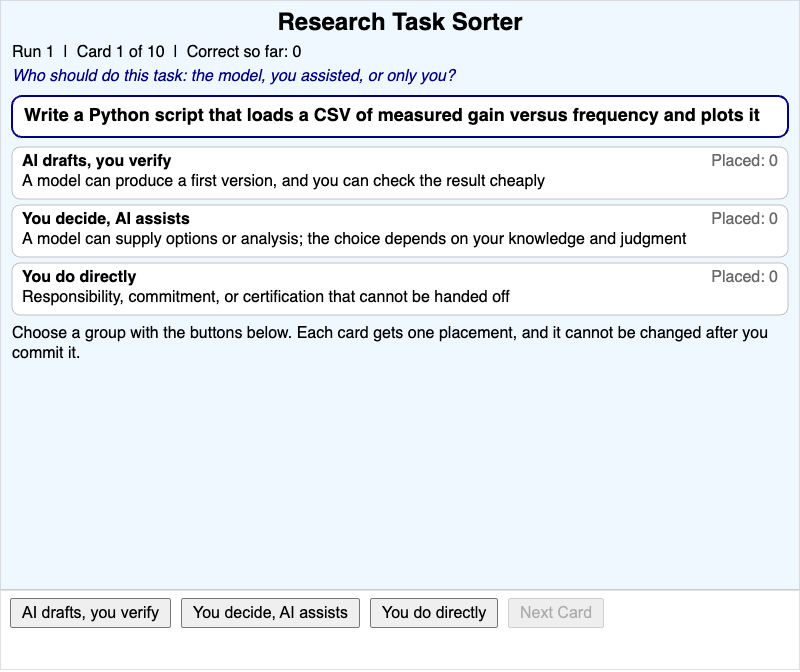
Sort ten everyday EE research tasks into "AI drafts, you verify", "You decide, AI assists", or "You do directly" and get immediate feedback on each placement.
-
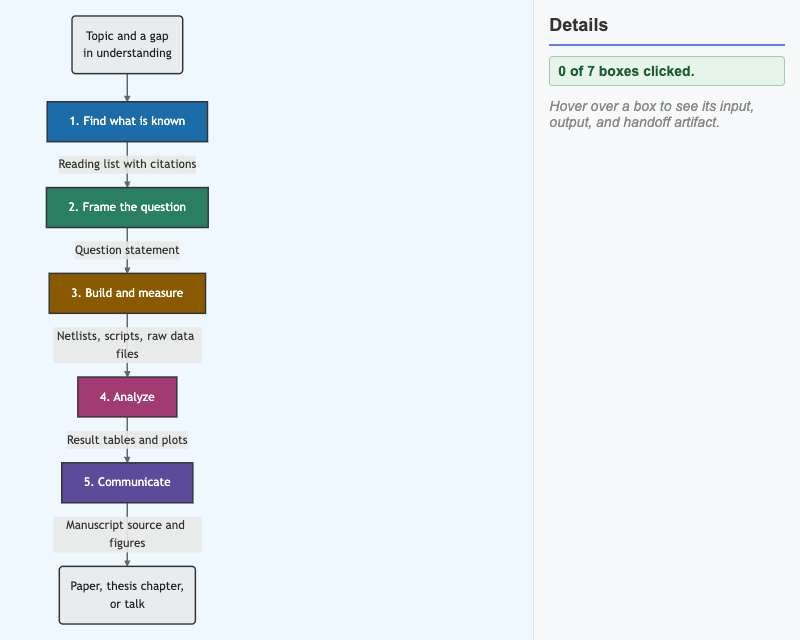
Interactive Mermaid flowchart of the five research workflow stages, with the handoff artifact on each arrow, a hover info panel, and a confetti cannon that fires when you have clicked every box.
-
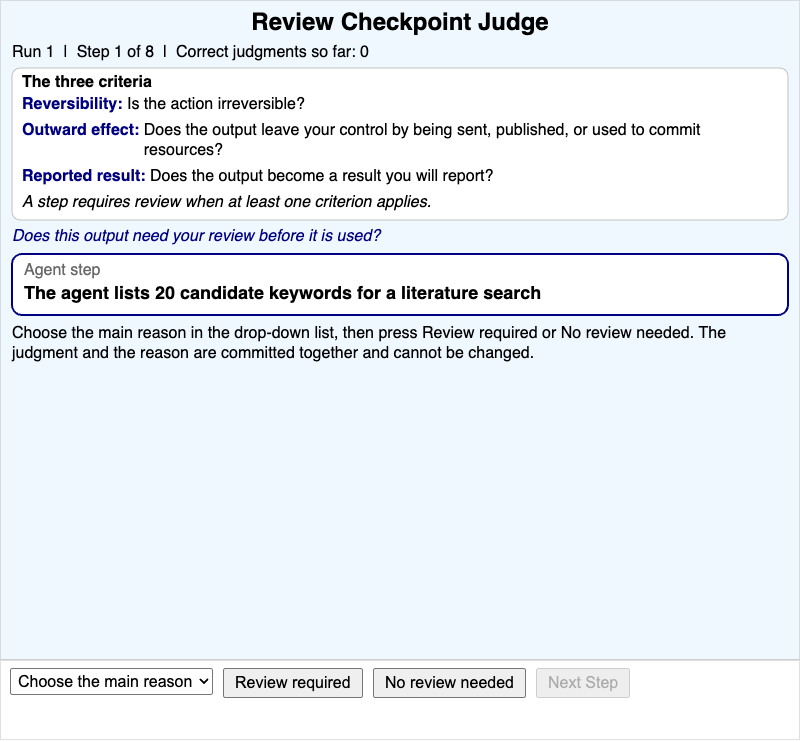
Judge whether each of eight agent steps in an analysis workflow needs your review before its output is used, and name the main reason - reversibility, outward effect, or reported result.
-
Search Query Precision and Recall Explorer
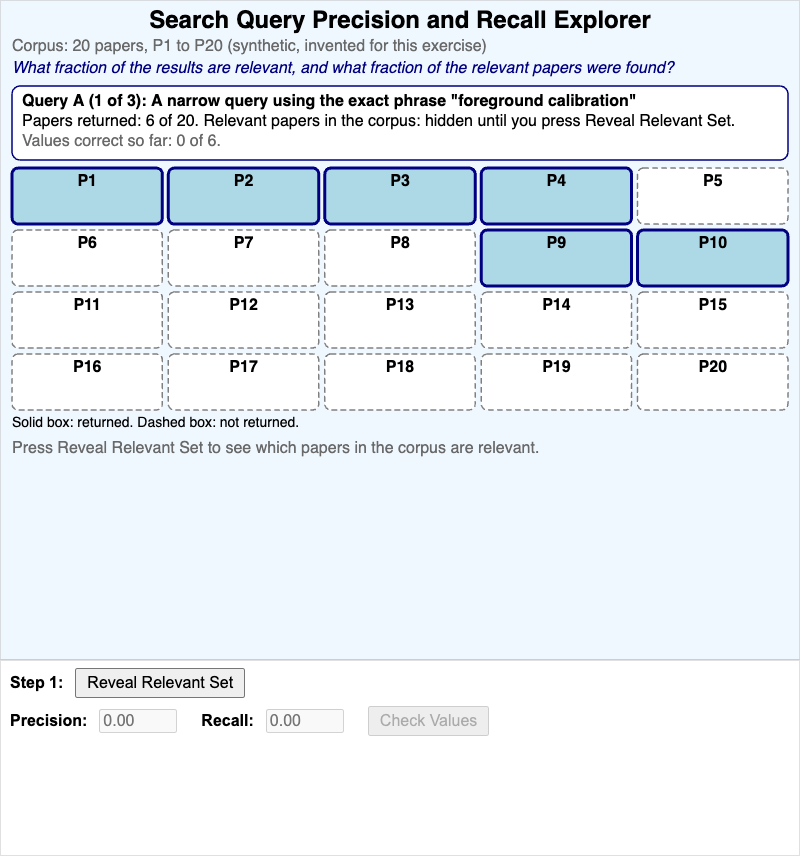
Calculate the precision and recall of three search queries on a synthetic corpus of twenty papers with eight relevant papers, then choose the query that suits a literature survey that cannot miss a relevant paper.
-
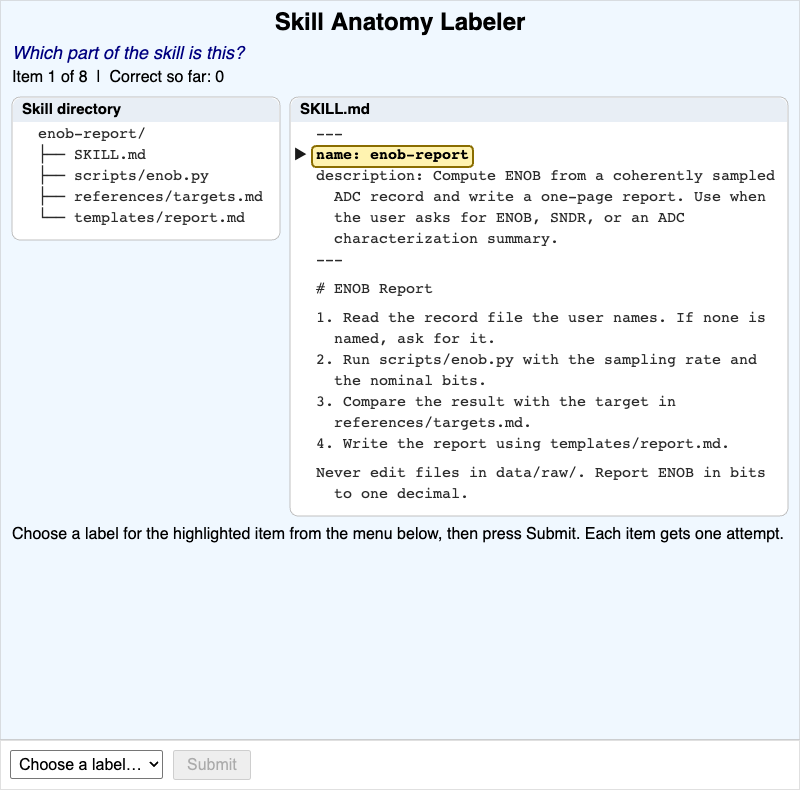
Interactive p5.js MicroSim in which learners identify eight lines and files of the enob-report agent skill as the skill name, the skill description, skill instructions, or a supporting file.
-
Skill Description Trigger Tester
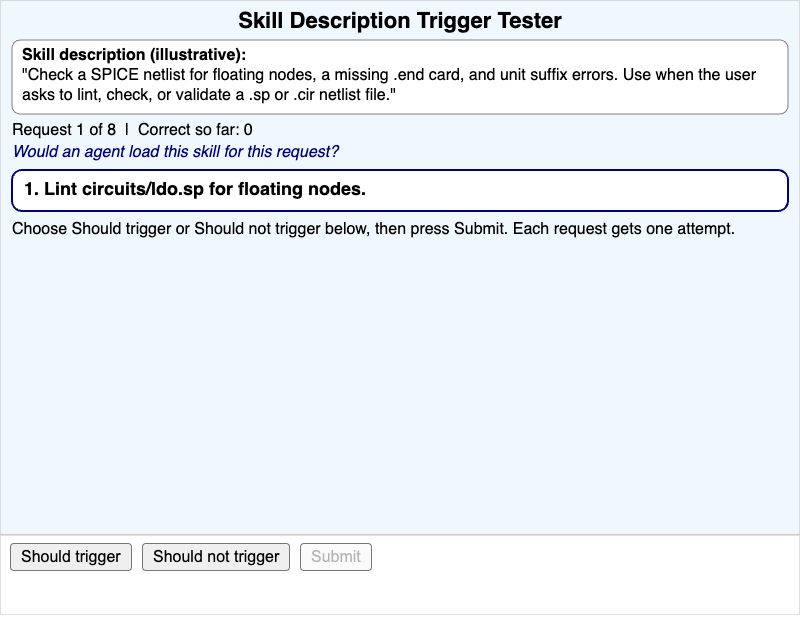
Decide, for eight user requests, whether an illustrative SPICE netlist-checking skill description should trigger, and learn to separate the task a request asks for from the keywords it shares.
-
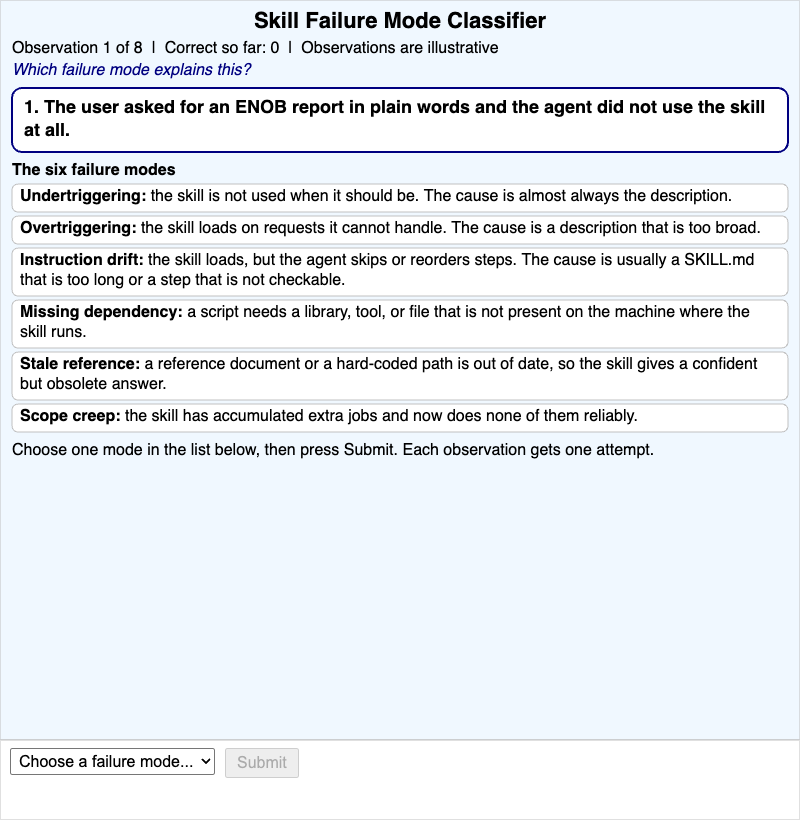
Attribute eight illustrative observations of a misbehaving agent skill to one of six failure modes, then see the recommended fix for each mode you missed.
-
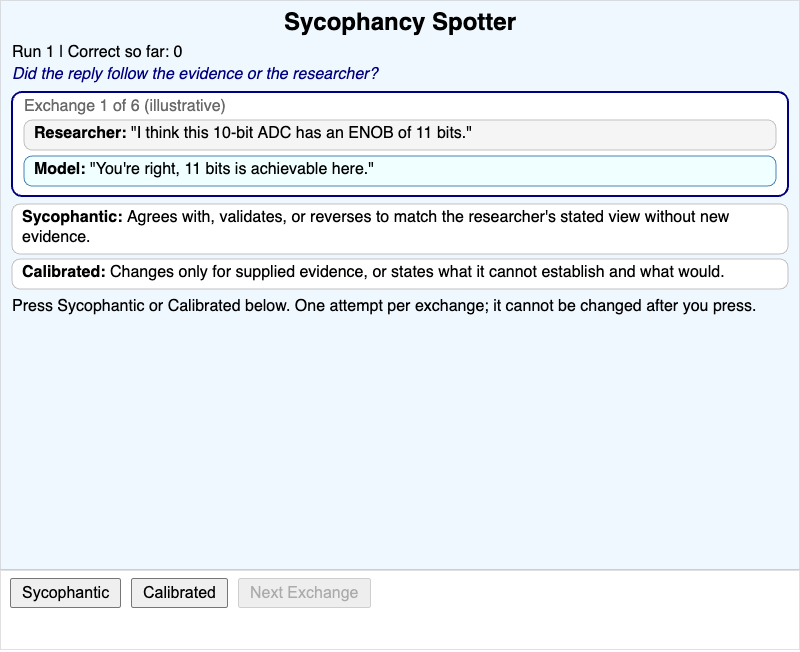
Classify the model reply in each of six illustrative researcher-model exchanges as sycophantic or calibrated, and get the reason after every choice.
-
Task Dependency Critical Path Scheduler
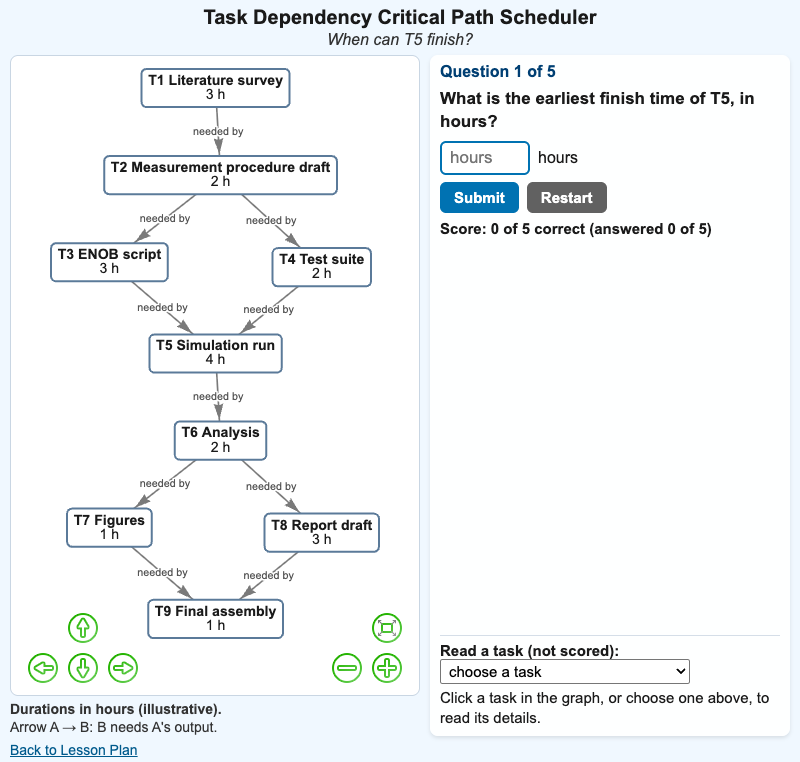
Interactive vis-network MicroSim in which learners calculate earliest finish times, the critical path, slack, and the project duration for a nine-task dependency graph, then see how shortening one task moves the critical path.
-
Temperature Next-Token Explorer
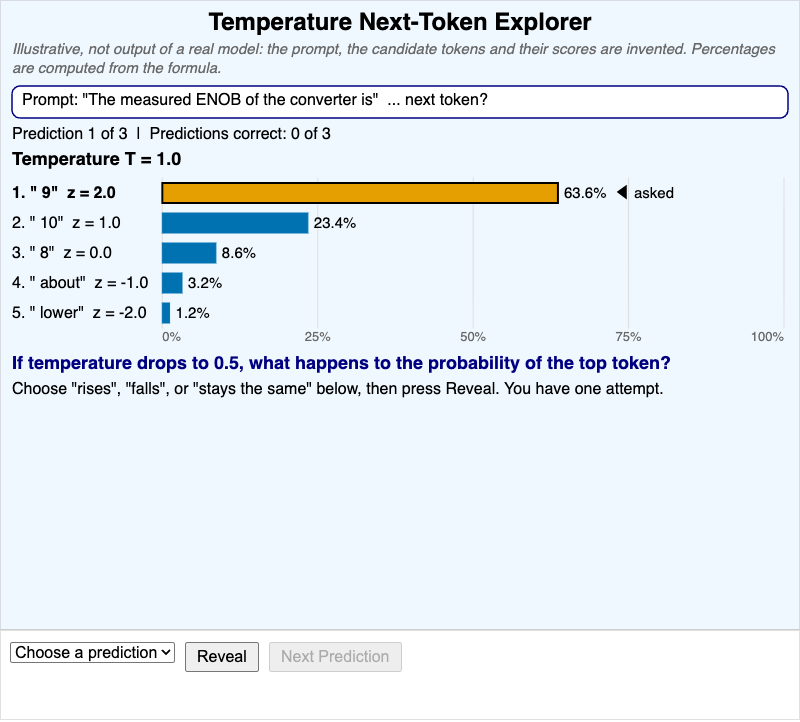
Predict whether the probability of the top-ranked and the lowest-ranked candidate token rises or falls when the sampling temperature changes, then reveal the new distribution and draw reproducible samples.
-
Unit Test Selector for Seeded Bugs
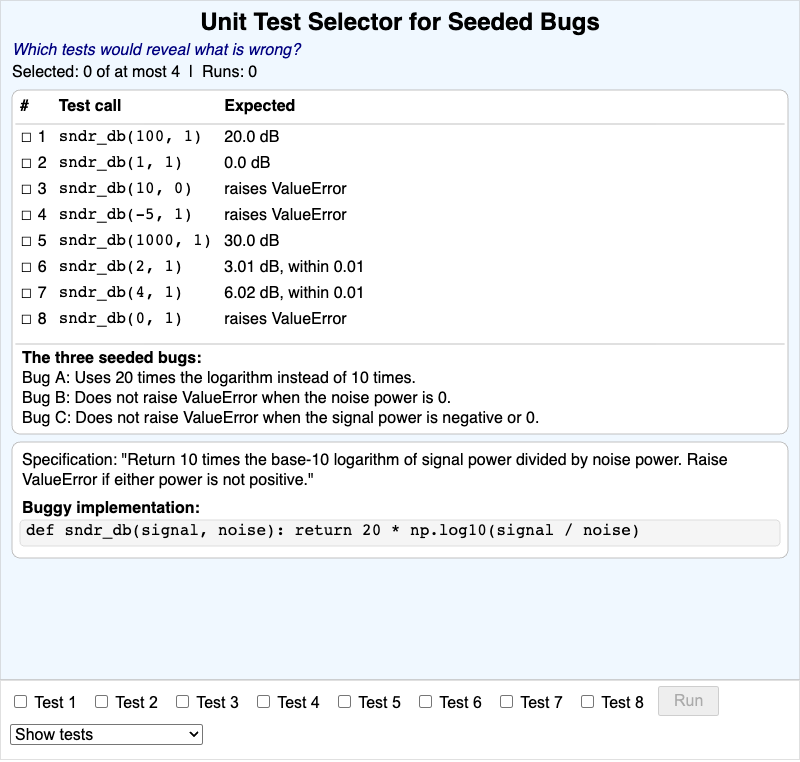
Select at most four of eight candidate unit tests for a buggy sndr_db() function and run them to see which of three seeded bugs your selection exposes and which stay hidden.
-
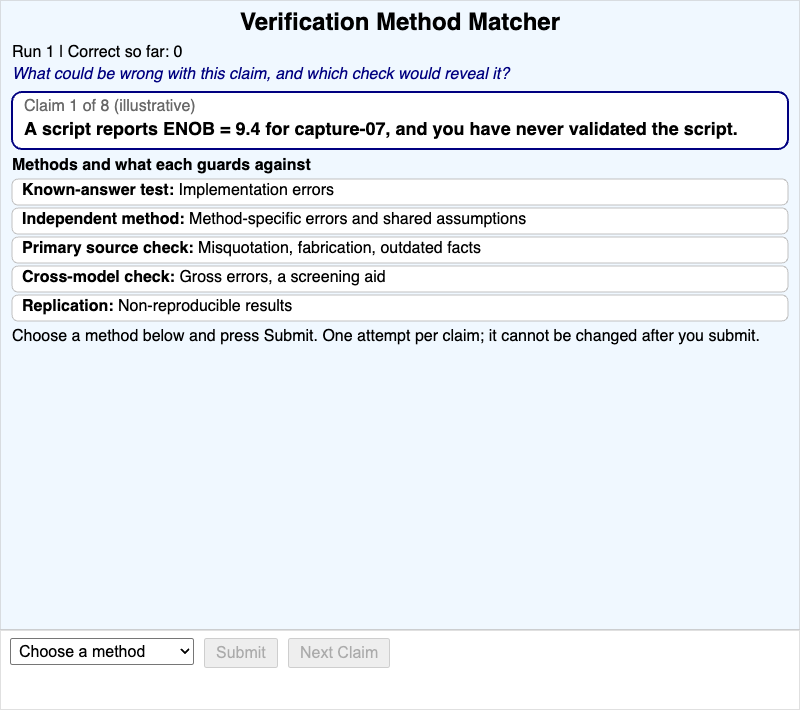
Recommend which of five verification methods (known-answer test, independent method, primary source check, cross-model check, replication) best fits each of eight illustrative AI-assisted claims, with feedback on every choice.